Digital Transformation • 5 hours ago • Neha Jamwal
For years, enterprise AI conversations have focused on models, computing power and increasingly sophisticated applications, but a quieter problem is now becoming impossible to ignore: the quality, structure and context of enterprise data may determine how far AI can actually scale.
That issue is becoming particularly important as organizations move from generative AI that produces content toward agentic AI that can reason across business information, make decisions and execute actions, because an agent cannot reliably operate on data that is fragmented, poorly governed, inaccessible or stripped of business context.
The timing is significant, with the Gartner Data & Analytics Summit in Mumbai this week putting AI-ready data, unstructured information, context and governance at the center of its discussions, while Gartner has also argued that AI-ready data needs to evolve toward agent-ready data as enterprises adopt autonomous systems.
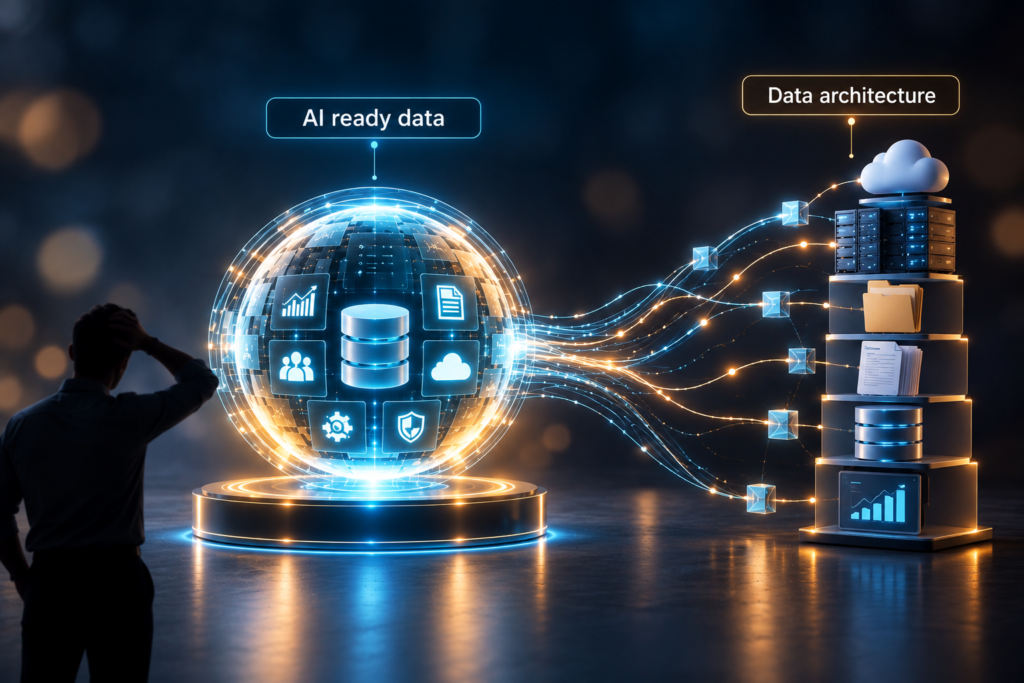
The result is a fundamental shift in the digital transformation conversation: AI readiness is increasingly becoming a data architecture problem rather than simply an AI implementation problem.
AI Does Not Fix a Broken Data Foundation
Enterprise organizations have spent years accumulating data across CRM platforms, ERP systems, data warehouses, data lakes, SaaS applications, collaboration tools, documents, emails, spreadsheets and specialized departmental systems.
The challenge is that this information was generally designed for human users and individual applications rather than for intelligent software that needs to discover, interpret and combine information across organizational boundaries.
A customer record might exist in a CRM, payment history in an ERP, support conversations in a service platform and contractual information in document repositories, with each system using different identifiers, structures and definitions.
A human employee can often bridge these gaps through experience and contextual knowledge, but an AI system needs that context to be represented much more explicitly if it is expected to reason reliably across the enterprise.
This becomes even more important when the AI is not simply answering a question but taking action based on the information it retrieves.
An incorrect summary may require human correction, but an agent acting on incorrect customer information, outdated pricing data or incomplete policy documentation can potentially create an operational error.
That is why data readiness is moving from being a supporting IT concern to becoming a central component of enterprise AI strategy.
The Shift From AI-Ready Data to Agent-Ready Data
The idea of AI-ready data initially centered on whether information was clean, accessible and suitable for analytics or machine learning, but agentic AI raises the requirements because agents need more than data availability.
They need to understand what the information represents, where it came from, whether it is current, how it relates to other information and whether they are permitted to use it for a particular decision.
Gartner has explicitly identified this evolution, noting that organizations need to assess whether enterprise data and data-management practices can support agentic AI, including whether agents can use particular data appropriately and safely.
This introduces a useful distinction between data that can be retrieved and data that can be trusted for action.
An enterprise may technically be able to retrieve a customer’s purchase history, for example, but an agent also needs to know whether the record is current, which customer identity it corresponds to, whether returns are included, which transactions are still pending and what business rules apply to the information.
That contextual layer is becoming one of the most important pieces of the emerging AI architecture.
Context Is Becoming Infrastructure
The traditional data stack has largely been designed around storing, processing, querying and analyzing information, but AI agents introduce another requirement: they need a reliable understanding of what the information means within a particular business environment.
This is why concepts such as metadata, semantic layers, knowledge graphs, data catalogs, lineage and contextual retrieval are becoming increasingly important in enterprise AI architecture.
Gartner’s September 2026 Data & Analytics Summit messaging in India specifically identified context as critical infrastructure, arguing that AI agents need governed and contextual access to the right data rather than simply access to larger quantities of information.
The distinction is subtle but important because more data does not necessarily produce better AI.
An agent given access to thousands of disconnected documents may actually have more opportunities to retrieve conflicting information, misunderstand terminology or rely on outdated material.
A smaller but well-governed information environment with clear relationships, definitions and provenance can therefore be more useful than a much larger collection of poorly organized enterprise content.
Unstructured Data Is Becoming a First-Class Enterprise Problem
One of the biggest complications is that some of the most valuable enterprise information does not live in neat database tables. Contracts, product documentation, customer conversations, technical manuals, policies, presentations, emails, meeting transcripts and support records can contain information that is essential to business decisions but difficult to represent in traditional structured data systems. That makes unstructured data management increasingly important as organizations expand AI use cases.
Gartner’s current Data & Analytics Summit discussions in Mumbai highlighted the need to extract, qualify and govern large volumes of unstructured information, including the use of entity extraction, embeddings and semantic enrichment alongside structured data pipelines. (Gartner EMT)
The implication is that enterprises cannot treat documents as a secondary information source anymore.
For an AI agent handling a procurement process, a contract clause may be just as important as a database record, while a customer-service agent may need both structured transaction data and unstructured conversation history to understand what happened. The data architecture therefore has to bring these different forms of information together without losing their provenance, permissions or business meaning.
Data Quality Becomes an Operational Issue
Data quality has traditionally been discussed in terms of reporting accuracy, analytics reliability and regulatory compliance, but agentic AI turns poor data quality into an operational risk. If an analytics dashboard contains an outdated figure, a human analyst may notice the discrepancy before making a decision, whereas an autonomous system may incorporate that figure directly into a workflow. That means organizations need to think about data quality in terms of fitness for action, not merely fitness for reporting.
The relevant questions become more demanding: Is the data current enough for this decision? Is the source authoritative? Can the agent distinguish between historical and active records? Does the information contain unresolved conflicts? Is the meaning consistent across systems? These questions make data observability, lineage and continuous validation increasingly important components of enterprise AI infrastructure.
Governance Has to Move Closer to the Data
Governance is often treated as a policy layer sitting above technology, but agentic AI makes governance much more operational because the system needs to know what information it can access and what it can do with that information. An agent working in finance may have access to invoices but not payroll information, while an HR agent may need access to employee records but should not automatically be permitted to retrieve unrelated financial data. This means that access control, identity, classification and policy enforcement increasingly need to work alongside the data architecture rather than being bolted on after an AI application has already been deployed.
Gartner’s September 2026 research highlights the connection, warning that organizations face significant AI governance challenges when data governance culture and practices do not evolve alongside AI adoption. The emerging architecture therefore needs to answer two questions simultaneously: Can the agent find this information? and Should the agent be allowed to use it?
That distinction will become increasingly important as agents move from retrieving information to initiating business actions.
The Data Platform Is Becoming Part of the AI Control Plane
The conventional data platform was primarily responsible for moving and managing information, but the agentic enterprise requires it to support a more dynamic relationship between data, applications and intelligent systems.
Agents need mechanisms for discovering relevant information, retrieving it in context, understanding its provenance, respecting access controls and feeding the resulting knowledge into a business workflow.
This is creating greater interest in architectures that combine structured and unstructured data, semantic layers, retrieval systems, knowledge representations, APIs and governance capabilities rather than treating each as a completely separate technology domain.
KPMG’s current AI-ready data roadmap similarly frames enterprise AI around data that can be discovered, interpreted, governed and reused across AI agents, retrieval systems and autonomous workflows.
The broader architectural shift is therefore from a data platform that primarily serves applications toward a data foundation that can also serve intelligent actors.
Modernization Does Not Necessarily Mean Replacing Everything
One of the biggest misconceptions around AI-ready architecture is that enterprises need to rebuild their entire technology environment before they can deploy meaningful AI. In reality, many organizations will need to work with decades of existing applications, databases and integration patterns while gradually making those environments more accessible to AI systems. The challenge is therefore less about replacing every legacy platform and more about creating reliable connective tissue between existing systems and new intelligent capabilities.
APIs, event streams, integration platforms, retrieval systems and semantic layers can become important bridges between older applications and newer AI workloads. This approach also changes the economics of transformation because organizations can prioritize the data and workflows that matter most to specific business outcomes rather than attempting an enormous technology replacement program before realizing any AI value.
AI Strategy and Data Strategy Can No Longer Be Separate
For years, organizations have often treated AI strategy as a technology initiative and data strategy as a separate enterprise discipline, but agentic AI makes that separation increasingly difficult to sustain. A business leader may identify an opportunity for an AI agent to automate customer onboarding, for example, but realizing that opportunity requires understanding where customer information lives, how identities are reconciled, which documents contain relevant policies, which decisions require approval and which systems need to be updated. The AI use case therefore creates a direct set of requirements for the data architecture.
This suggests a more effective planning model in which organizations start with a business outcome, identify the agent or AI capability required to achieve it and then work backward to determine the necessary data, context, integration and governance capabilities. That approach avoids investing blindly in data infrastructure without a clear business purpose while also preventing AI teams from discovering foundational data problems only after an application has already been built.
The New Data Architecture Is About Meaning
The next generation of enterprise data architecture will not be defined simply by where data is stored. It will increasingly be defined by whether machines can understand the relationships, definitions, permissions and business context surrounding that data. A customer should not simply be represented as a collection of database fields, for example, but as an entity whose relationships with accounts, transactions, contracts, interactions and service events can be understood consistently across the organization.
Similarly, a product should carry enough context for an agent to distinguish between active inventory, discontinued products, regional availability and contractual restrictions. This is where semantic models, metadata, lineage and knowledge structures become strategically important because they provide the connective tissue that allows AI systems to reason across enterprise information.
What Digital Transformation Leaders Should Prioritize
The first priority should be to identify the AI use cases that genuinely matter to the business, because data modernization becomes much easier to prioritize when tied to specific outcomes rather than treated as an abstract technology upgrade. Organizations can then map each use case to the structured and unstructured information it requires, identify where that information lives and determine which gaps could prevent the AI system from operating reliably.
The next priority should be establishing consistent definitions and ownership, because an agent cannot make sense of enterprise information when different departments use different meanings for the same customer, product, transaction or business metric. Governance should then be designed into the architecture, covering data quality, lineage, access, provenance, retention and appropriate use before autonomous execution expands.
Finally, organizations should continuously evaluate whether their data foundation remains suitable as AI capabilities evolve, because the requirements of a system that generates content are not identical to those of an agent that can make decisions and execute workflows.
Key Takeaways
- AI readiness is becoming a data architecture challenge, because enterprise AI depends on the quality, accessibility and context of the information behind the models.
- Agent-ready data goes beyond AI-ready data, requiring information to be understandable, contextual, governed and suitable for machine-driven action.
- Context is becoming critical infrastructure, with metadata, semantic layers, lineage and knowledge structures helping agents understand what enterprise information actually means.
- Unstructured data can no longer remain an afterthought, because contracts, documents, conversations and policies often contain information required for meaningful AI decisions.
- Data quality is becoming an operational concern, as incorrect or outdated information can increasingly influence automated decisions and workflows.
- Governance needs to move closer to the data, ensuring that agents can determine not only what information exists but also whether they are authorized to use it.
- Modernization does not require replacing every legacy system, because integration, APIs, retrieval systems and semantic layers can connect existing technology to new AI capabilities.
- AI strategy and data strategy are converging, with successful enterprise AI increasingly requiring business leaders, data teams and technology teams to design the foundation together.
Conclusion
The enterprise AI race is often described as a competition between models, platforms and applications, but the deeper competitive question may be whether organizations can make their own information understandable and trustworthy enough for intelligent systems to use. An enterprise can deploy an impressive AI model and still struggle to create business value if its customer records conflict, its documents remain inaccessible, its definitions vary between departments or its governance policies cannot be enforced at the point of action.
That is why the next stage of digital transformation will increasingly focus on the data foundation beneath AI rather than the AI interface sitting above it.
The organizations preparing for agentic AI therefore need to think beyond data lakes, warehouses and pipelines and start designing for context, meaning, provenance, permissions and action. AI may provide the intelligence, but the enterprise data architecture determines what that intelligence can actually understand and do. As AI moves from generating answers to executing work, being AI-ready may no longer be enough; enterprises will need data that is ready for agents to act on.